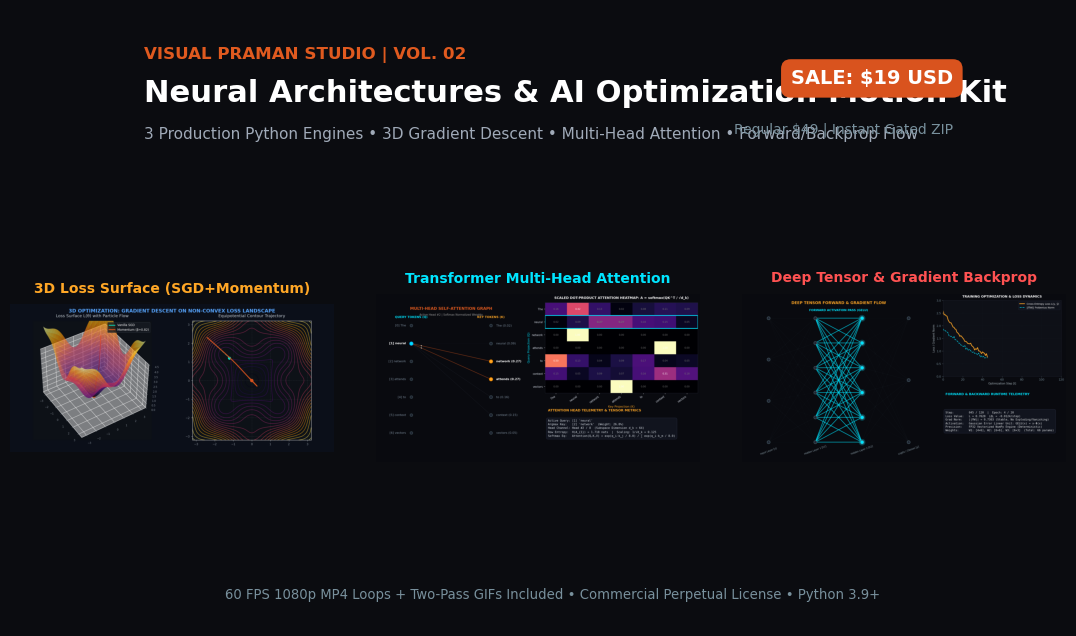
Description
Where Rigorous Machine Learning Theory Meets Editorial Motion Design
Engineered by Dr. Shrikant Bhosale and the Visual Praman Studio, this kit solves the most frustrating bottleneck facing AI researchers, technical educators, and tech creators: creating publication-grade visual motion graphics of complex deep learning architectures without dealing with bulky 3D software or fragile dependencies.
What’s Inside The Kit
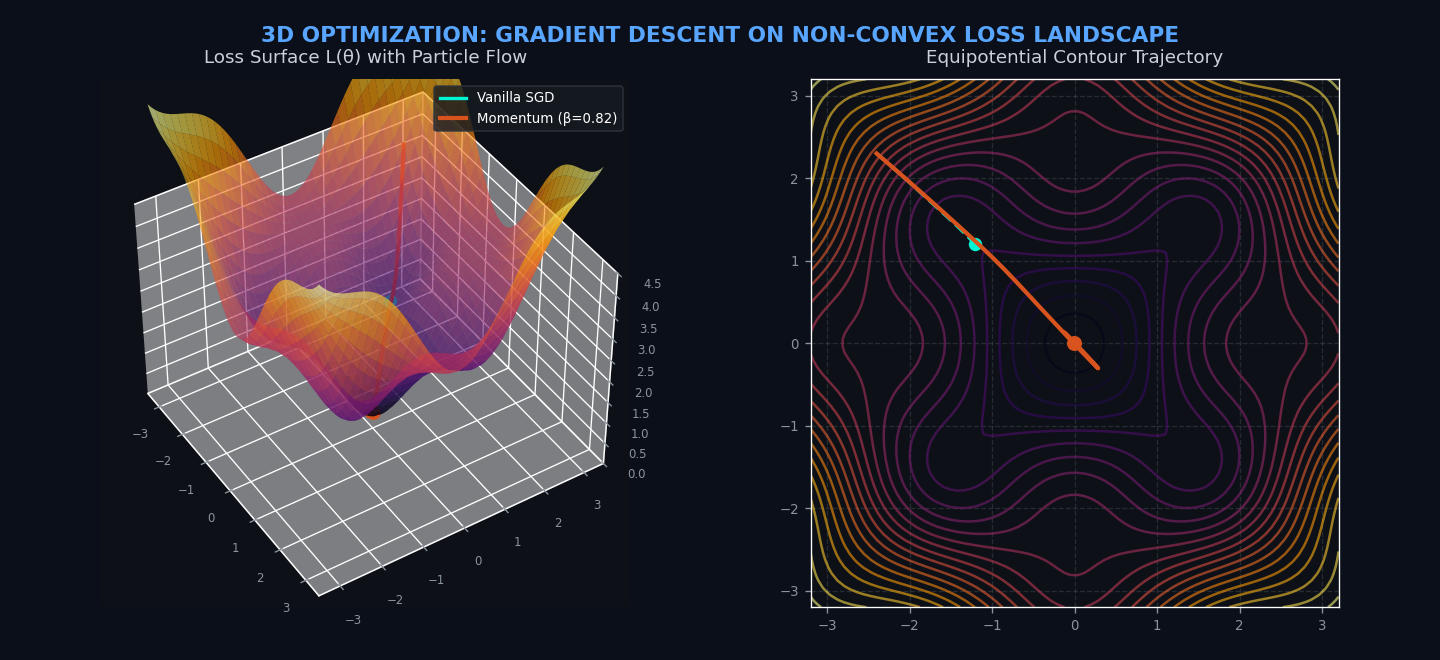
1. 3D Gradient Descent & Loss Landscapes
Simulates multi-agent non-convex optimization comparing Vanilla SGD versus Momentum ($v_t = gamma v_{t-1} + eta nabla L$). Features real-time dynamic elevation contour projections, saddle point evasion dynamics, and an active HUD telemetry read-out.
01_gradient_descent_3d_optimization.py01_gradient_descent_3d_60fps.mp401_gradient_descent_3d_loop.gif
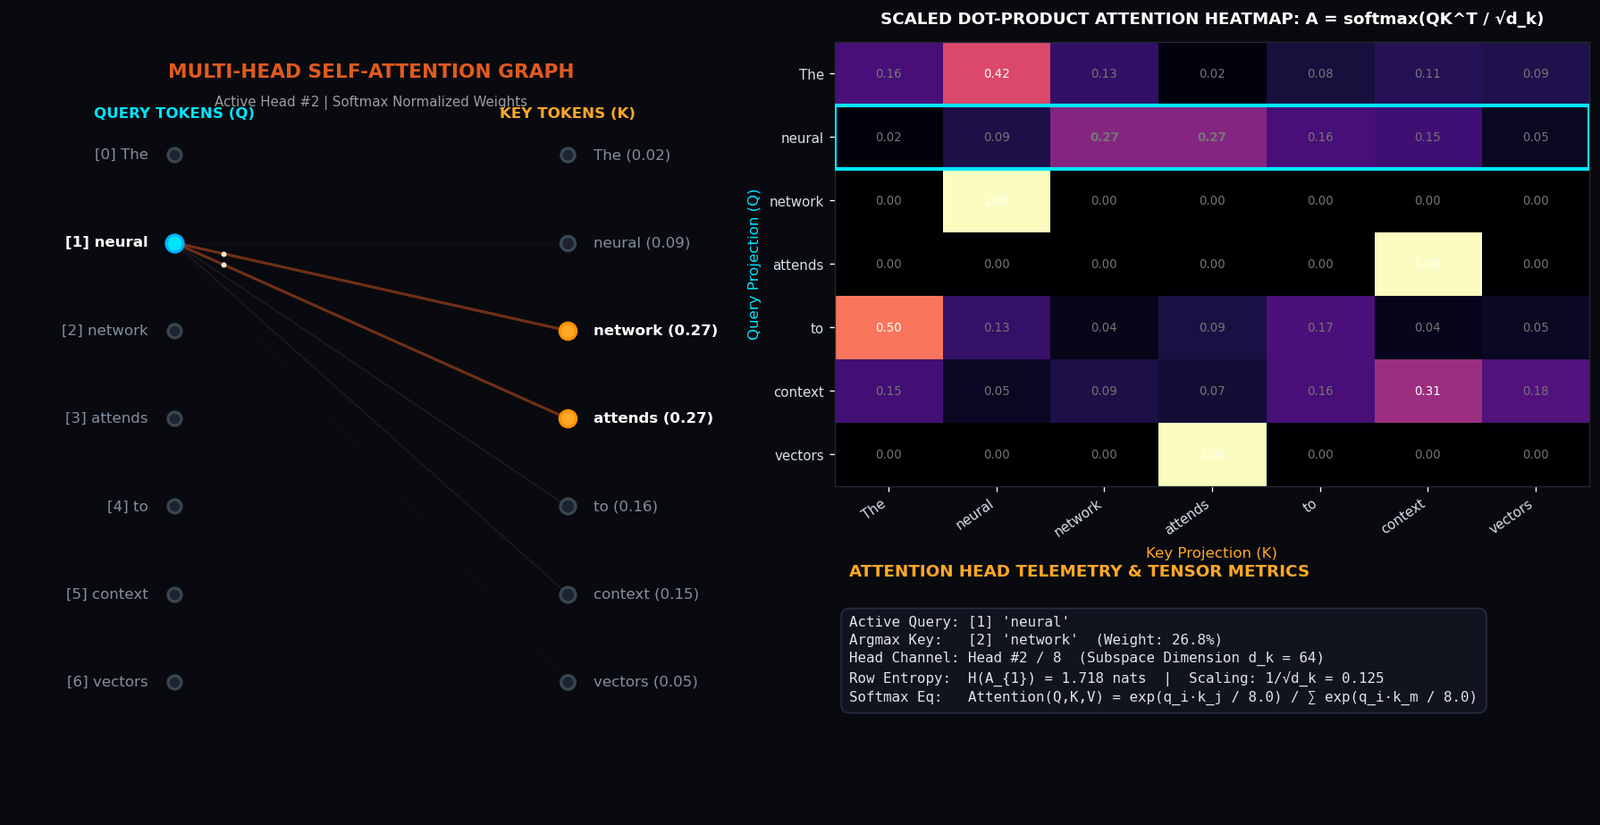
2. Transformer Scaled Dot-Product Attention
Visualizes multi-head self-attention: $text{Attention}(Q, K, V) = text{softmax}left(frac{QK^T}{sqrt{d_k}}right)V$. Shows bipartite token interaction splines with animated particle pulses, synchronized N×N heatmap matrix, and dynamic row entropy telemetry.
02_transformer_self_attention_matrix.py02_transformer_self_attention_60fps.mp402_transformer_self_attention_loop.gif
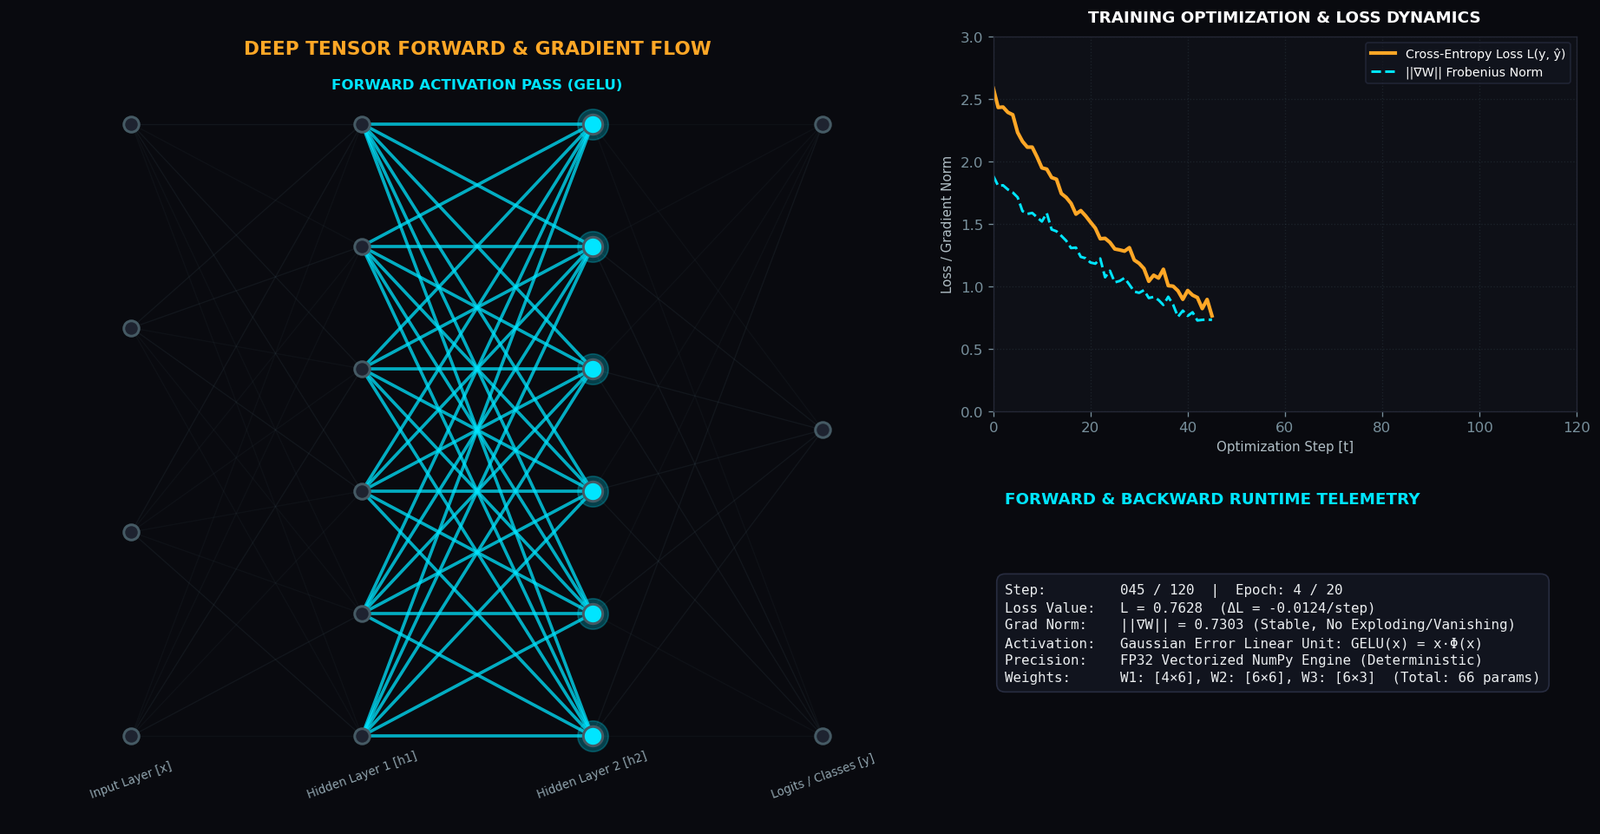
3. Deep Tensor Forward & Gradient Backprop Flow
Visualizes forward activation propagation using Gaussian Error Linear Units (GELU) and reverse backpropagation gradient waves ($frac{partial mathcal{L}}{partial W}$). Includes live loss convergence curve and Frobenius norm stability monitor.
03_neural_activation_forward_flow.py03_neural_activation_flow_60fps.mp403_neural_activation_flow_loop.gif
Directory Tree & Package Manifest
neural_architectures_ai_motion_kit_vol2/
├── 01_gradient_descent_3d_optimization.py   # 3D Loss surface & multi-agent optimizer
├── 02_transformer_self_attention_matrix.py   # Multi-head attention & bipartite graph
├── 03_neural_activation_forward_flow.py     # Deep tensor activation & backprop pulses
├── requirements.txt                         # Zero heavy dependencies (NumPy, Matplotlib)
├── README.md                                # Comprehensive parameter guide & 4K setup
├── LICENSE.txt                             # Perpetual Royalty-Free Commercial License
└── renders/
    ├── 01_gradient_descent_3d_60fps.mp4     # Master 1080p 60fps loop
    ├── 01_gradient_descent_3d_loop.gif      # Two-pass lanczos palette GIF
    ├── 02_transformer_self_attention_60fps.mp4
    ├── 02_transformer_self_attention_loop.gif
    ├── 03_neural_activation_flow_60fps.mp4
    └── 03_neural_activation_flow_loop.gif
Technical Specifications
| Engine Stack | Pure Python 3.9+, NumPy, Matplotlib, FFmpeg |
| Render Resolution | 1920×1080 (1080p Full HD) scalable to 4K UHD (3840×2160) |
| Frame Rate | 60 FPS and 30 FPS seamless cycle loops |
| License Scope | Perpetual, worldwide commercial usage rights for YouTube, Substack, courses, and client decks |
| Delivery Format | Instant SHA-256 verified .ZIP download upon checkout |
Frequently Asked Questions
Can I use this in monetized YouTube videos or paid courses?
Yes. The license explicitly grants perpetual, worldwide commercial rights for video, newsletters, client decks, and educational products.
Do I need a high-end GPU to run the Python scripts?
No. All math is fully vectorized in NumPy and renders on any standard laptop or workstation without CUDA or GPU requirements.
Reviews
There are no reviews yet.